My trajectory through “Machine Learning in ActionMachine Learning in Action” is becoming more unpredictable as we go – this time, rather than completing our last episode on K-means clustering (we’ll get back to it later), I’ll make another jump directly to Chapter 14, which is dedicated to Singular Value Decomposition, and convert the example from Python to F#.
The chapter illustrates how Singular Value Decomposition (or SVD in short) can be used to build a collaborative recommendation engine. We will follow the chapter pretty closely: today we will focus on the mechanics of using SVD in F# – and leave the recommendation part to our next installment.
Until this point, I have avoided using a Linear Algebra library, because the algorithms we discussed so far involved lightweight, row-centric operations, which didn’t warrant taking such a dependency. SVD is one of these cases where using an established library is a good idea, if only because implementing it yourself would not be trivial. So let’s create a new script file (Chapter14.fsx), add a reference to Math.NET Numerics for F# to our project via NuGet, and reference it in our script:
Now that we have our tools, let’s start working our example. Imagine that we are running a website, where our users can rate dishes, from 1 (horrendous) to 5 (delightful). Our data would look something along these lines:
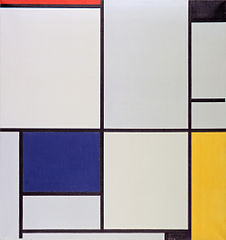
Mondrian is one of those modern painters whose work everyone recognizes, even though few people will quote his name. He also happens to be one of my favorite artists - in spite of their simple geometric structure, I find his pieces strangely beautiful:
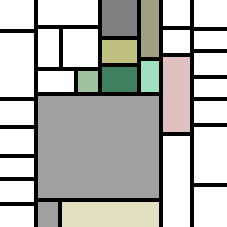
I have been hard at work on some pretty dry stuff lately, and needed a bit of a change of pace, and ended up spending a couple of hours coding a simple Mondrianizer in F#: give it a picture, and it will transform it into something ‘in the style of Mondrian’.
For instance, starting from my Twitter avatar, here is what the Mondrianizer produces:
This was strictly quick-and-dirty hackery, so the code is not my best by any stretch of the imagination, but I was rather pleased by the results - you can find the current version of the Mondrianizer here on GitHub.
Recently, I had a few interesting discussions on F# code readability. One argument I often hear about F# is that by virtue of its succinctness, it increases the signal-to-noise ratio. I certainly found this to be true: when the entire code fits on your screen, and you don’t have to scroll around to figure out what is going on, navigating a code base becomes significantly simpler. Relatedly, because the F# syntax is so much lighter than C#, some of my coding habits evolved. I stick to the “one public type per file” guideline in C#, and initially did the same in F#.
That didn’t last long: declaring a Record Type in F# is a one-liner, and dedicating an entire file to it seems… overkill:
As a result, my F# solutions tend to contain less files, and each file is more “self-contained”, usually declaring a couple of types and implementing some operations involving these types in a module. Again, less navigation required: open one file, and the truth, the whole truth, and nothing but the truth is right there on your screen.
In my experience, this also makes refactoring tools much less important in F# than C#. The lack of refactoring tools in F# used to be one of my main gripes with using the language. At that point, I don’t really care that much any more, because I don’t really need them that badly. Sure, it would be nice to propagate a rename automatically – but lots of the refactoring tools I commonly use with C# deal with navigating around or moving pieces of code from file to file (extract class, method, etc…), all problems that are minor when your code sits in just a couple of files, and the “what class owns what responsibility” issue vanishes because your functions are at a module level.
Conversely, I have found myself annoyed a few times looking at F# code where succinctness erred on the side of obfuscation. This tendency for terse naming conventions seems to be a cultural heritage from other functional languages, and makes sense to an extent – functional code tends to focus on applying generic transformations to “things”, and not that much on what the “thing” might be.
As an illustration, I have seen often code along these lines:
matchlistwith|x::xs->...
No need to go full onJava on your code, but a bit of naming effort goes a long way in making code intelligible:
Another readability aspect I found interesting with F# code is that the order of declarations matters, and the order of the files in the project matters as well. This seemingly odd constraint has a good reason – it makes the awesome F# type inference work.
Over time, I actually began to appreciate this not as a constraint, but almost as a feature. One problem I keep running into when I look into a C# code base I am not familiar with is “damn! where should I start?”. There is no clear way to proceed through the code, and I have ended up countless times navigating haphazardly from class to class, hoping to stumble upon a solid starting point.
I don’t really have that problem with F# code bases – essentially, I either start from the first line of the first file, and read forward, or the last line of the last file, working my way back. Either way works; the first one reads like a constructive proof, walking you every step to the ineluctable conclusion, the second one starts with the “high point” of the code base, digging progressively into the nitty-gritty and assumptions that were made to get there.
Someone reacted by saying that I was “just rationalizing”. There is probably some truth in that – but I believe there is something to be said for having a natural reading order in a code base. As a side-note, this is also one of my minor annoyances with GitHub: in the browser, the files from an F# repository are displayed in alphabetical order, which loses the logical project organization.
I might also change my tune when I have to deal with a truly large F# code base, which hasn’t happened to me yet. At that point, I may long for more freedom in organizing my code, and, say, arrange it by topical folders. For the moment, though, this hasn’t been an issue for me!
And the Journey converting “Machine Learning in Action” from Python to F# continues! Rather than following the order of the book, I decided to skip chapters 8 and 9, dedicated to regression methods (regression is something I spent a bit too much time doing in the past to be excited about it just right now), and go straight to Unsupervised Learning, which begins with the K-means clustering algorithm. So what is clustering about? In a nutshell, clustering focuses on the following question: given a set of observations, can the computer figure out a way to classify them into “meaningful groups”? The major difference with Classification methods is that in clustering, the Categories / Groups are initially unknown: it’s the algorithm’s job to figure out sensible ways to group items into Clusters, all by itself (hence the word “unsupervised”). Chapter 10 covers 2 clustering algorithms, k-means , and bisecting k-means. We’ll discuss only the first one today. The underlying idea behind the k-means algorithm is to identify k “representative archetypes” (k being a user input), the Centroids. The algorithm proceeds iteratively:
Starting from k random Centroids,
Observations are assigned to the closest Centroid, and constitute a Cluster,
Centroids are updated, by taking the average of their Cluster,
Until the allocation of Observation to Clusters doesn’t change any more.
When things go well, we end up with k stable Centroids (minimal modification of Centroids do not change the Clusters), and Clusters contain Observations that are similar, because they are all close to the same Centroid (The wikipedia page for the algorithm provides a nice graphical representation).
In spite of being color blind, I am a visual guy - I like to see things. Nothing beats a chart to identify problems in your data. I also spend lots of time manipulating data in FSI, the F# REPL, and while solutions like FSharpChart makes it possible to produce nice graphs fairly easily, I still find it introduces a bit of friction, and wondered how complicated it would be to use Excel as a charting engine.
Turns out, it’s not very complicated. The typical use case for generating charts in Excel is to first put data in a spreadsheet, and use the corresponding range as a source for a chart. However, it’s also perfectly possible to directly create a Chart object, and manipulate its SeriesCollection, adding and editing Series, which are arrays of XValues and Values.
As a starting point, I decided to focus on 2 problems:
plotting functions, in 2 and 3 dimensions,
producing scatterplots.
Both are rather painful to do in Excel itself - and scatterplots are the one chart I really care about when analyzing data, because it helps figuring out whether or not some variables are related.
What I wanted was a smooth experience from FSI - start typing code, and ship data to Excel, without having to worry about the joys of the Excel interop and its syntax. The video below shows what I ended up with, in action.
Note: watching me type is about as exciting as watching paint dry, so I sped up the video from its original 5 minutes down to 2 - otherwise there is no trick or editing.
This year’s blockbuster: plotting functions from F# to Excel